Claude Fable 5.2 vs Opus 5.5, GPT-6 Astra, Gemini 4 Carbon
9 min read

In Anthropic's November 9, 2026 table, Claude Fable 5.2 leads 10 of the 11 benchmarks shown against Claude Opus 5.5, GPT-6 Astra and Gemini 4 Carbon. The one exception is AutomationBench, where Gemini 4 Carbon scores 53.9% against Fable 5.2's 51.4%. The whole table is Anthropic's; there is no independent reproduction.
This post is a news roundup and compilation; I have not tested the models. The numbers come from the table on Anthropic's announcement page. The rival models' numbers are also from Anthropic's table, not third-party measurements. For an introduction to the model, see What Is Claude Fable 5.2, and for price differences, pricing and cost.
The short answer
Fable 5.2 has the highest scores on the benchmarks Anthropic chose. The biggest gaps are WANDR (82.1%, Opus 5.5 72.3%), Remote Labor Index (41.3%, Opus 5.5 21.3%, roughly double) and RoboDojo Sim (64.9%, Opus 5.5 39.4%). The smallest gap is Chartography: Fable 5.2 73.4%, Gemini 4 Carbon 72.5%, GPT-6 Astra 71.0%. Carbon leads on AutomationBench, and Opus 5.5 on the unlabeled Elo row under AA-Briefcase.
Anthropic's table
Columns: Claude Fable 5.2, Fable 5.1, Claude Opus 5.5, GPT-6 Astra, Gemini 4 Carbon. "-" means Anthropic did not show that cell. Scores are at each model's highest accessible effort unless noted.
| Benchmark | Fable 5.2 | Fable 5.1 | Opus 5.5 | GPT-6 Astra | Gemini 4 Carbon |
|---|---|---|---|---|---|
| FrontierCode 2.0 (agentic coding) | 49.1% (Xhigh) | 32.4% (Xhigh) | 45.5% | 42.8% | 41.1% (Medium) |
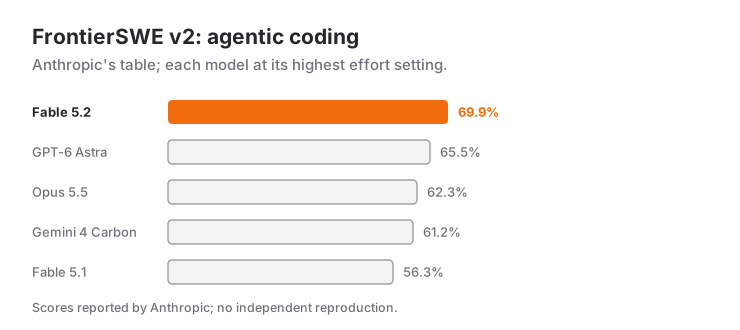
| FrontierSWE v2 (agentic coding) | 69.9% | 56.3% | 62.3% | 65.5% | 61.2% |
| AutomationBench (workflows) | 51.4% | 31.4% | 42.5% | 41.4% | 53.9% |
| Terminal-Bench-Science 0.1 (scientific research) | 74.6% | 52.6% | 58.7% | 68.1% | 64.8% |
| OSWorld 2.1 (computer use, offline subset) | 89.3% | 83.5% | 87.2% | 79.5% | 81.5% |
| RoboDojo Sim (robotics; Anthropic internal run) | 64.9% | 27.6% | 39.4% | 29.8% | - |
| AA-Briefcase v1.1 (knowledge work, rubric) | 66.1% | 61.5% | 61.2% | 52.0% | 61.8% |
| Remote Labor Index (High effort) | 41.3% | 17.9% | 21.3% | 20.8% | - |
| Humanity's Last Exam (with tools) | 74.2% | 65.6% | 67.7% | 57.2% | - |
| Chartography (chart understanding, no tools) | 73.4% | 44.8% | 64.4% | 71.0% | 72.5% |
| WANDR (agentic search, relaxed score) | 82.1% | 68.7% | 72.3% | - | - |
Two more rows outside the table: under AA-Briefcase there is an unlabeled Elo row (Fable 5.2 1785, Fable 5.1 1669, Opus 5.5 1800, GPT-6 Astra 1569, Gemini 4 Carbon 1611). On BenchCAD 2.1 (hardware engineering, with tools, 0-100 partial score, Max effort) Fable 5.2 scored 83.5, Opus 5.5 65.3 and Fable 5.1 44.4.
Coding and agentic work
Fable 5.2 leads on both agentic coding benchmarks, but the gaps are single digits. On FrontierCode 2.0 it scores 49.1% at Xhigh effort (Opus 5.5 45.5%, Astra 42.8%, Carbon 41.1% at Medium). On FrontierSWE v2 it scores 69.9%, with GPT-6 Astra second at 65.5%. Anthropic also says that on FrontierCode 2.0 at High effort Fable 5.2 scores 45.3%, level with Opus 5.5's best (45.5%), but at roughly half the cost per task (details are in the pricing post).
Note: Carbon's FrontierCode 2.0 score is shown at Medium effort in the table, not at the same effort level as Fable's Xhigh. The reason is not given, so comparing these two numbers one to one would not be right.
AutomationBench (workflows) is a different story: Fable 5.2 made a big jump from Fable 5.1 (31.4% to 51.4%), but Carbon leads at 53.9%. On Terminal-Bench-Science 0.1 Fable 5.2 scores 74.6% and Astra is second at 68.1%.
If you want a hands-on tool comparison, meaning how Claude, ChatGPT, Cursor and Codex hold up on real work, the vibe coding tools comparison is about usage, not benchmarks.
Computer use, vision and robotics
On computer use the gap is small; in robotics it is large. On the OSWorld 2.1 offline subset Fable 5.2 scores 89.3%, Opus 5.5 87.2%, Carbon 81.5% and Astra 79.5%: a 2.1-point gap to the nearest rival.
Chart understanding (Chartography, no tools) is nearly level: Fable 5.2 73.4%, Carbon 72.5%, Astra 71.0%, Opus 5.5 64.4%.
In robotics, on RoboDojo Sim, Fable 5.2 scores 64.9%; Opus 5.5 39.4%, Astra 29.8%, Fable 5.1 27.6%. This is Anthropic's internal run; Anthropic says it is more than double Astra and Fable 5.1. Gemini 4 Argon, which appears only in this chart, scored 34.2%. Carbon is not shown on this row.
Knowledge work and reasoning
On the knowledge-work and reasoning rows Fable 5.2 leads, with one exception. On AA-Briefcase v1.1 (rubric) it scores 66.1%; Carbon 61.8%, Opus 5.5 61.2%. On Humanity's Last Exam with tools it scores 74.2% (Opus 5.5 67.7%, Astra 57.2%). On Remote Labor Index at High effort it scores 41.3%, Opus 5.5 21.3%, Astra 20.8%. On WANDR it scores 82.1%, Opus 5.5 72.3%; Astra and Carbon are not shown on this row.
Where Fable 5.2 does not lead
There are three points:
- AutomationBench. Gemini 4 Carbon 53.9%, Fable 5.2 51.4%. This is the only benchmark in the table where Fable 5.2 trails.
- The unlabeled Elo row under AA-Briefcase. Opus 5.5 1800, Fable 5.2 1785. The row's label is not in Anthropic's table, so I could not verify what it measures and I am not interpreting it.
- Closeness on Chartography. Fable 5.2 73.4%; Carbon 72.5% and Astra 71.0% narrow the gap to 1-2 points. Saying "won" on this row would go beyond the precision of the measurement.
The footnote also says the safeguards are on for Fable 5.2, Fable 5.1 and Opus 5.5 only; no condition is stated for GPT-6 Astra and Gemini 4 Carbon.
How to read this table
- The table is the producer's. Anthropic chose the benchmarks. I have no evidence of a bias toward its own model in that choice, but as an outsider I cannot rule it out either.
- The conditions of rivals' scores are unclear. The footnotes do not give the source or conditions of the GPT-6 Astra and Gemini 4 Carbon scores. In the Google table as I relayed it in my Carbon post, GPT-6 Astra scores 65.5% and Carbon 61.2% on FrontierSWE 2, and Opus 5.5 scores 87.2% and Carbon 81.5% on OSWorld-2.1; these four numbers match Anthropic's table. So on at least these rows the two producers give the same values (I am quoting my own post and did not re-verify Google's page).
- On CyScenarioBench each lab's score rests on its own tasks. Those rows cannot be compared directly.
- No independent measurement. I did not read a Fable 5.2 result from Artificial Analysis or any other third party. I also did not read the system card.
- Benchmarks in other posts are different runs. Do not mix values such as Terminal-Bench 4.0 or OSWorld 2.1 at 80.1% from my other posts with this table: different versions and runs. The numbers in the Gemini 4 Carbon, Argon, Opus 5.5 and Astra comparison, for example, belong to their own sources.
- Mythos 5.2 is a separate line. The unprotected model scores 75.3% on Terminal-Bench-Science (next to Fable 5.2's 74.6%) and 89.6% on CVE Rediscovery in the cyber benchmarks; these are not Fable's rows. Mythos is closed to general access.
Which model for which job
Here is what can be inferred from the benchmark table, but do not decide before measuring on your own work:
| Job | Signal in the table |
|---|---|
| Hard, long-running agentic coding | Fable 5.2 has the top scores (FrontierCode 2.0, FrontierSWE v2) |
| Workflow automation | Carbon leads on AutomationBench; Fable 5.2 second |
| Computer use | Fable 5.2 ahead, Opus 5.5 close |
| Chart and visual understanding | Fable 5.2, Carbon and Astra very close |
| Robotics, search, scientific research | Fable 5.2 clearly ahead |
| Price first | Opus 5.5 is half the price per token ($4 / $20), but cost per task varies by job |
The new work Fable 5.2 has produced (1,000 agents, Fermat, physics) is covered in the what-can-it-do post. For access, see the who-can-use-it post.
Frequently Asked Questions
Is Claude Fable 5.2 better than Opus 5.5?
On all 11 benchmarks in Anthropic's table Fable 5.2 is ahead of Opus 5.5. Only on the unlabeled Elo row under AA-Briefcase is Opus 5.5 (1800) ahead of Fable 5.2 (1785). The table is Anthropic's; there is no independent verification.
(Note: I did not count that Elo row among the benchmarks, because Anthropic gives it without a label.)
Is Fable 5.2 better than GPT-6 Astra?
In the table Fable 5.2 scores higher than Astra on every benchmark where both are shown. The closest row is Chartography: 73.4% against 71.0%. The conditions of Astra's scores are not stated in Anthropic's footnotes.
Does Gemini 4 Carbon beat Fable 5.2?
On AutomationBench, yes: 53.9% against 51.4%. On Chartography Fable 5.2 scores 73.4% and Carbon 72.5%. Fable 5.2 leads on most of the other rows.
Where does Fable 5.2 have the biggest lead?
Against Opus 5.5 it is 82.1% vs 72.3% on WANDR, 41.3% vs 21.3% on Remote Labor Index and 64.9% vs 39.4% on RoboDojo Sim. RoboDojo is Anthropic's internal run.
Is Fable 5.2 the best coding model?
On the two agentic coding benchmarks in Anthropic's table (FrontierCode 2.0, FrontierSWE v2) Fable 5.2 has the highest score. The gaps are 3.6 and 4.4 points. I did not read an independent coding comparison; try it on your own codebase before saying "best."
Can I trust these benchmark results?
The numbers are Anthropic's own reporting; there is no third-party reproduction. The source and conditions of the rival numbers are not stated. Run a small trial on your own work before deciding.
Why is Sonnet 5.5 not in this table?
Anthropic's Fable 5.2 table does not include Sonnet 5.5. See the separate post for Sonnet 5.5; there is no shared run that would let me merge its benchmarks with this table.
Sources
- Anthropic, Claude Fable 5.2 and Claude Mythos 5.2 (November 9, 2026; editing note added November 11): benchmark table, footnotes, RoboDojo and Mythos rows, cost charts.
- Anthropic, Claude Fable product page: comparison with Fable 5.1, model timeline.
- Anthropic, Models overview: Claude Fable 5.2: model properties, prices and the Opus 5.5 and Sonnet 5.5 comparison.
- Anthropic, What's new in Claude Fable 5.2: effort and behavior notes.
Related Posts
What Is Claude Fable 5.2? Price, Mythos, Access
Anthropic released Claude Fable 5.2 on Nov 9, 2026: 1M context, $8 input and $40 output per million tokens, 20% cheaper than Fable 5.1.
Claude Fable 5.2 Pricing: $8 / $40 and Effort Levels
Claude Fable 5.2 costs $8 input and $40 output per million tokens. How caching, Batch, fast mode and effort levels change cost per task, with a worked example.
Gemini 4 Carbon vs Argon vs Claude Opus 5.5 vs GPT-6 Astra
Gemini 4 Carbon is first on the index but not everywhere: Opus 5.5 leads agentic coding, Astra leads FrontierSWE, and its error rate is higher than Argon's.